
You.com Launches Inference Router: 12 Open-Weight Models With 99.9% Uptime SLA
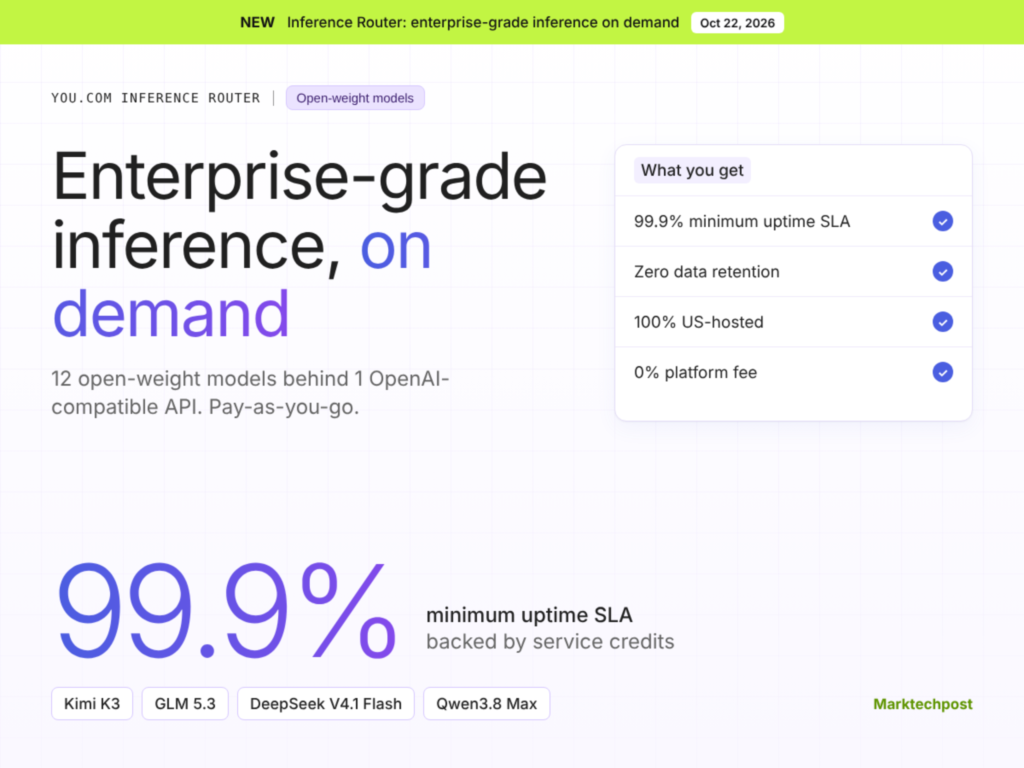
You.com has launched Inference Router, a managed API for running open-weight models in production. The You.com Inference Router is an OpenAI-compatible service that routes requests across 12 live models. It bundles a 99.9% minimum uptime SLA and zero data retention (ZDR). It adds 100% US hosting and server-side web search. It is pay-as-you-go, with no platform fee.
TL;DR
Size: 12 live models, from GPT-OSS 120B (125K context) to Kimi K3 and Qwen3.8 Max (1M context). Kimi K3 is a 2.8T-parameter model; Qwen3.8 Max is a 2.4T MoE.
Runs on: Fully managed. Requests hit You.com Inference Direct first, then fail over to US-hosted partners. No GPUs to manage.
Performance: On You.com’s LiveNewsBench run, open-weight models plus You.com search matched frontier models at lower cost.
Best: GLM-5.3 with You.com search scored 86.53%, at $0.0485 per question versus $0.0920 for Claude Sonnet 5.5 (self-reported).
Worst: Per-token prices sit near market. Kimi K3 is $2.85/$14.25, only 5% below Together AI’s $3.00/$15.00.
It is one API for many open-weight models. The endpoint is https://api.you.com, with OpenAI-compatible and Anthropic-compatible routes. Existing SDK code moves over by changing the base URL and key.
You.com team frames the problem around stalled migrations. Dev teams test open-weight models on aggregators, then hit security review. Reviewers ask about ZDR, US hosting, access controls and DPAs. Dedicated providers clear those bars, but usually with a large commitment. Inference Router targets that gap.
How does the routing and failover work?
Every request goes first to You.com Inference Direct, the company’s own inference capacity. If it is down or full, the request fails over to a vetted partner. The official post names Parasail, Wafer, Alibaba Cloud, Meta and Inception, with Prime Intellect coming soon. All are 100% US-hosted and must meet ZDR rules.
Failover does not change the bill. Each model has 1 published per-token price. You.com also offers spend caps per API key and daily usage views by model, cost and provider. Accounts run on SOC 2 compliant infrastructure, with a DPA on request.
What does zero data retention cover?
The ZDR policy states that prompts and outputs are processed in memory and not stored. It covers both model calls and web search requests. You.com keeps only operational metadata, such as token counts, timestamps and account IDs. Prompt hashes, de-identified text and disk-backed prompt caches are explicitly excluded.
Which models are available, and what do they cost?
The models page lists 12 live models, all US-hosted. Prices are per 1M tokens (input / output):
Kimi K3 (Moonshot AI): $2.85 / $14.25, 1M context
Qwen3.8 Max (Alibaba): $1.85 / $5.55, 1M context
GLM 5.3 (Z.ai): $1.35 / $4.25, 1M context
DeepSeek V4 Pro: $1.65 / $3.65, 1M context
DeepSeek V4.1 Flash: $0.30 / $1.20, 1M context
Mercury 3 (Inception): $0.10 / $0.35, 1M context
GPT-OSS 120B (OpenAI): $0.097 / $0.73, 125K context
Muse Wonder, Muse Spark 1.3, GLM 5.3 Flash, Qwen3.8 Flash and MiniMax M3 round out the list.
How does built-in web search work?
Developers declare a web_search or web_extract tool, and the router runs searches for the model. The docs show up to 20 results per search and a default of 30 search rounds. Responses return a web_results object with citations.
Search runs on the same server as the model. You.com says internal tests show up to 15% lower latency.
What do the benchmarks show?
You.com reports a LiveNewsBench run of 1,329 questions, using Braintrust’s open-source search eval. These numbers are self-reported:
DeepSeek V4.1 Flash costs about 77% less per question than Claude Sonnet 5.5. It trails by 2.26 points.
Braintrust’s own August study used older models. There, DeepSeek V4 Flash with You.com search hit 80.66% at $0.0163 per question. Claude Sonnet 5 with built-in search scored 78.78% at $0.1148.
You.com also cites joint work with NVIDIA and CoreWeave. Post-training Nemotron 3.5 Lightning with You.com search in the loop lifted BrowseComp from 36.97% to 45.45%. Tool calls fell by 30%.
How does it compare with OpenRouter, Together AI and Fireworks AI?
The clearest price win is versus Fireworks’ US-only tier. There, You.com is about 37% cheaper on Kimi K3 input.
Key Takeaways
12 open-weight models behind 1 OpenAI-compatible base URL.
At least 99.9% uptime SLA on pay-as-you-go, with credits.
ZDR covers both model calls and web search.
0% platform fee versus OpenRouter’s 5.5%.
Token prices are near market; the value is in guarantees.
Check out the launch post, browse the model list and check the developer docs. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.