
Google Unveils TPU 8i Max and TPU 8tx: A Dual-Chip TPU and a Confidential TPU
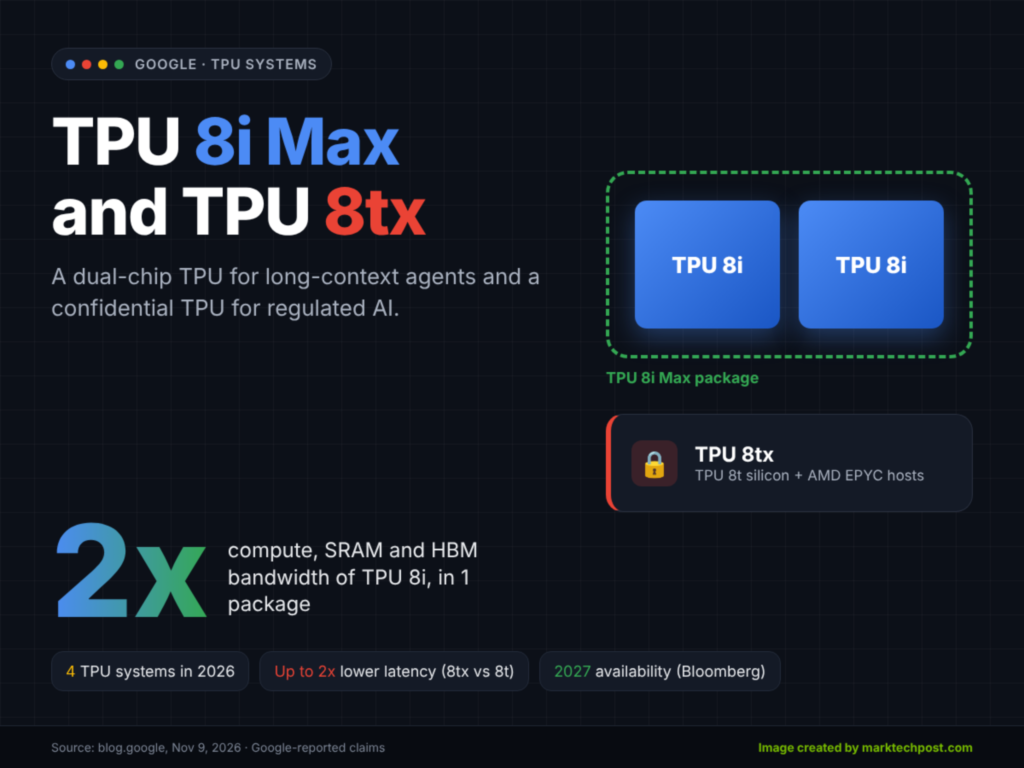
Google has added two new systems to its eighth-generation TPU lineup. TPU 8i Max targets massive context windows and rack density. TPU 8tx targets secure, confidential inference. Google TPU 8i Max is a dual-chip package built from 2 TPU 8i chips. Both arrive alongside TPU 8t and TPU 8i, announced in April.
TL;DR
Size: TPU 8i Max = 2 TPU 8i chips in 1 package. TPU 8tx = TPU 8t silicon plus 5th Gen AMD EPYC hosts.
Runs on: Google Cloud TPU systems.
Performance: 8i Max doubles TPU 8i compute, SRAM and HBM bandwidth. 8tx cuts latency up to 2x versus TPU 8t.
Best: 2x the silicon in the existing rack footprint (TPU 8i Max).
Worst: No absolute specs, benchmarks, prices or regions published for either system.
What did Google announce?
Google announced both systems today. These are new system configurations, not new chips. Google reuses its existing eighth-generation silicon and changes packaging, hosts, memory and networking around it.
How does TPU 8i Max work?
TPU 8i Max attacks the memory wall. Google team combines 2 low-latency TPU 8i chips onto 1 package. The result doubles compute, SRAM and HBM bandwidth compared with TPU 8i.
Each TPU 8i chip is rated at 10.1 PFLOPS of FP4, 288 GB of HBM and 8,601 GB/s. It also carries 384 MB of on-chip SRAM. Doubling those figures implies about 20.2 PFLOPS FP4, 768 MB SRAM and 17.2 TB/s per package. Google did not publish these absolute figures. It also did not state HBM capacity for TPU 8i Max.
TPU 8i Max fits twice the silicon in the existing rack footprint. Google positions it for agents working across whole codebases or hours of video.
What makes TPU 8tx different?
TPU 8tx is built for regulated enterprises and governments. It keeps data and model weights protected even while in active use. Normally, data must be decrypted in memory during processing.
TPU 8tx uses the same silicon as TPU 8t. It pairs that silicon with 5th Gen AMD EPYC CPU hosts. It also adopts the Boardfly network from TPU 8i. Google claims up to 2x lower latency than TPU 8t, with a near-zero security penalty.
Teams can fine-tune, distill and run reinforcement learning on 1 system. That avoids moving sensitive data between separate clusters.
What changed in the TPU software stack?
TorchTPU: Open-sourced last month, it runs PyTorch and Hugging Face models natively. vLLM and SGLang get TPU backends.
TPU agent suite (preview): Plugs into Claude Code, Cursor and Antigravity for onboarding and kernel tuning.
TPU Sync: An open-source C++ library that tiers KV cache across HBM, host DRAM and storage.
Agent Compute Engine: Suspends idle agent sessions and moves working memory off-chip. Preview is targeted for the coming months.
Cloud Pathways and GKE dynamic slicing: Both are now GA. Dynamic slicing cuts job startup up to 5x and speeds fault recovery up to 4.5x.
On Qwen3 235B, TPU Sync dropped median KV transfer latency from several seconds to about 230 ms. TTFT fell 60% on average for 235B and 90% for 480B under low concurrency. These tests ran on Ironwood (TPU v7x), not the new systems.
How do the numbers compare?
Derived = 2x Google’s published TPU 8i per-chip figures. TPU 8t values come from Google’s technical deep dive.
Key Takeaways
TPU 8i Max puts 2 TPU 8i chips in 1 package.
It doubles TPU 8i compute, SRAM and HBM bandwidth.
TPU 8tx brings confidential inference to TPU 8t silicon.
TPU Sync cut KV transfer latency over 90% on Ironwood.
Check out the official announcement, the TPU 8t and 8i deep dive, and the TPU Sync repo. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.