
A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation
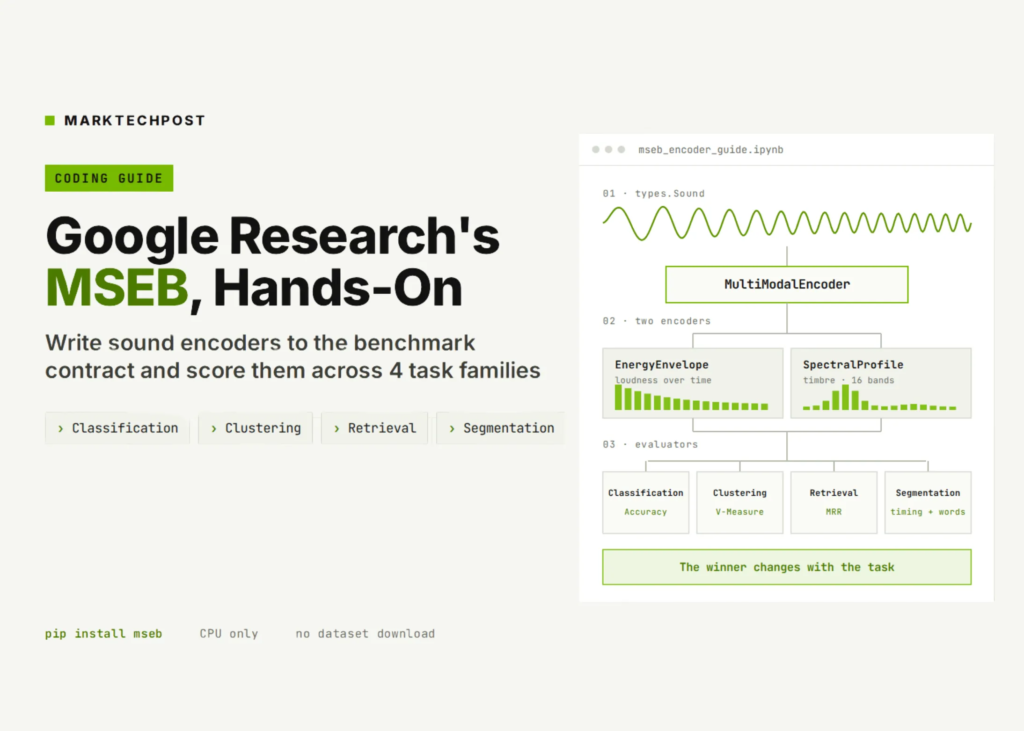
In this tutorial, we work with MSEB, the Massive Sound Embedding Benchmark from Google Research, and approach it from the perspective of what a leaderboard number actually means: the evaluator surface. We install the package and map its three layers, then write two deliberately different encoders against the framework’s own abstract base class: one that measures loudness over time and one that measures timbre, and encode a small synthetic corpus we generate in the notebook so nothing has to be downloaded. We drive the classification, clustering, retrieval, and segmentation evaluators over those embeddings, call the metric functions directly to see what each one rewards, and finish by assembling the TaskMetadata a real submission carries. The result is a comparison in which the two encoders trade places depending on which evaluator is asked, which is the argument for a multi-task benchmark made in numbers rather than in prose.
import sys
import json
import math
import traceback
import subprocess
import numpy as np
RESULTS = {}
BENCH = {}
def banner(title):
print(“\n” + “=” * 78)
print(title)
print(“=” * 78)
def section(name):
def wrap(fn):
def run(*a, **kw):
banner(name)
try:
out = fn(*a, **kw)
RESULTS[name] = out if isinstance(out, str) else “ok”
return out
except Exception as e:
RESULTS[name] = f”SKIPPED / FAILED -> {type(e).__name__}: {e}”
print(f”\n[!] {name} did not complete: {type(e).__name__}: {e}”)
traceback.print_exc(limit=3)
return None
return run
return wrap
banner(“0. Install MSEB and map the three layers we will use”)
subprocess.run([sys.executable, “-m”, “pip”, “install”, “-q”, “mseb==0.1.0″], check=True)
import mseb
from mseb import types, encoder as encoder_lib, evaluator as evaluator_lib, metrics
from mseb.evaluators import (
classification_evaluator,
clustering_evaluator,
retrieval_evaluator,
segmentation_evaluator,
)
print(f” mseb {mseb.__version__} | Python {sys.version.split()[0]} | numpy {np.__version__}”)
print(“\n MSEB is three layers, and a benchmark run walks down them:”)
print(” types -> Sound, SoundEmbedding, Score, TaskMetadata: the shapes every task speaks”)
print(” encoder -> MultiModalEncoder: the contract YOUR model implements”)
print(” evaluators -> classification, clustering, retrieval, reranking, transcription, segmentation, …”)
print(“\n evaluator entry points we will drive:”)
for module, cls in [(classification_evaluator, “ClassificationEvaluator”),
(clustering_evaluator, “ClusteringEvaluator”),
(retrieval_evaluator, “RetrievalEvaluator”),
(segmentation_evaluator, “SegmentationEvaluator”)]:
print(f” {module.__name__.split(‘.’)[-1]:28s} {cls}”)
print(“\n Everything below runs on CPU with no dataset download: we synthesise the audio.”)
We install mseb and import the three layers that a benchmark run walks down. The types module holds the shapes every task speaks, Sound, SoundEmbedding, Score and TaskMetadata; the encoder module holds MultiModalEncoder, the contract our own model implements; and the evaluators package holds one module per task family. We import only the four evaluators this notebook drives, because the classification, clustering, retrieval, and segmentation modules depend on nothing heavier than NumPy and scikit-learn. In contrast, the reranking and transcription evaluators pull in Whisper and the task runner pulls in TensorFlow and apache-beam. Everything below therefore runs on a free CPU runtime with no dataset download and no accelerator.
@section(“1. The type contract: Sound, SoundEmbedding, Score”)
def type_contract():
t = np.arange(SR) / SR
waveform = (0.5 * np.sin(2 * np.pi * 440 * t)).astype(np.float32)
sound = types.Sound(
waveform=waveform,
context=types.SoundContextParams(id=”demo_000″, sample_rate=SR, length=len(waveform),
language=”en_us”, text=”a 440 Hz tone”),
)
print(f” Sound id={sound.context.id!r} {sound.waveform.shape} @ {sound.context.sample_rate} Hz”
f” -> {sound.size_bytes:,} bytes”)
embedding = types.SoundEmbedding(
embedding=np.zeros((1, 16), dtype=np.float32), # (N, D): one utterance-level vector
timestamps=np.array([[0.0, 1.0]], dtype=np.float32), # (M, 2): [start, end] in seconds
context=sound.context,
encoding_stats=types.EncodingStats(input_size_bytes=sound.size_bytes, embedding_size_bytes=16 * 4),
)
print(f” SoundEmbedding embedding{embedding.embedding.shape} timestamps{embedding.timestamps.shape}”
f” -> {embedding.size_bytes} bytes”)
print(f” compression_ratio = {embedding.encoding_stats.compression_ratio:.5f}”
f” ({1 / embedding.encoding_stats.compression_ratio:,.0f}x smaller than the audio)”)
print(” N embeddings and M timestamps: M == N is frame-aligned, M == 1 is utterance-level.”)
print(” `embedding` may also hold N strings instead of vectors – step 8 uses exactly that.”)
score = types.Score(metric=”Accuracy”, description=”Overall classification accuracy”,
value=0.875, min=0.0, max=1.0)
print(f”\n Score {score.metric}={score.value} in [{score.min}, {score.max}] :: {score.description}”)
for bad, why in [(dict(metric=””, description=”d”, value=0.5, min=0.0, max=1.0), “empty metric name”),
(dict(metric=”m”, description=”d”, value=0.5, min=1.0, max=0.0), “min > max”)]:
try:
types.Score(**bad)
except Exception as e:
print(f” rejected at construction ({why}): {type(e).__name__}: {e}”)
return f”Sound {sound.size_bytes:,} B -> embedding {embedding.size_bytes} B”
type_contract()
We start with the type contract, because every other layer is expressed in it. A Sound carries a waveform, along with SoundContextParams, the identifier, sample rate, length, language, and optional transcript, which follow the audio through the whole pipeline. A SoundEmbedding carries an array of N embeddings and an array of M timestamp pairs, and the relation between N and M is the benchmark’s vocabulary: M equal to N means one vector per frame, while M equal to one means a single utterance-level vector, which is what our encoders produce. EncodingStats records the input and embedding sizes and exposes compression_ratio, here a thousandfold reduction from audio to vector. A Score is a metric name, a value and its bounds, and it validates itself at construction, rejecting an empty metric name or a minimum above its maximum, so a malformed number cannot reach a leaderboard. The embedding field also accepts N strings instead of N vectors, which is the door that step 8 walks through.
“””Baseline: average energy in `n_bins` equal time slices. Loud/quiet, nothing about timbre.”””
def __init__(self, n_bins: int = 16):
super().__init__()
self.n_bins = n_bins
def _setup(self):
self._ready = True # a real encoder loads weights here
def _check_input_types(self, batch):
for item in batch:
if not isinstance(item, types.Sound):
raise ValueError(f”{type(self).__name__} takes types.Sound, got {type(item).__name__}”)
def _encode(self, batch) -> list[types.SoundEmbedding]:
out = []
for sound in batch:
slices = np.array_split(sound.waveform.astype(np.float32), self.n_bins)
vec = np.array([[float(np.sqrt(np.mean(s ** 2) + 1e-12)) for s in slices]], dtype=np.float32)
vec /= np.linalg.norm(vec) + 1e-9
out.append(types.SoundEmbedding(
embedding=vec,
timestamps=np.array([[0.0, sound.context.length / sound.context.sample_rate]], dtype=np.float32),
context=sound.context))
return out
class SpectralProfileEncoder(encoder_lib.MultiModalEncoder):
“””Contender: mean log-magnitude spectrum pooled into `n_bands` bands. Describes timbre.”””
def __init__(self, n_bands: int = 16, frame: int = 512):
super().__init__()
self.n_bands, self.frame = n_bands, frame
def _setup(self):
self._window = np.hanning(self.frame).astype(np.float32)
def _check_input_types(self, batch):
for item in batch:
if not isinstance(item, types.Sound):
raise ValueError(f”{type(self).__name__} takes types.Sound, got {type(item).__name__}”)
def _encode(self, batch) -> list[types.SoundEmbedding]:
out = []
for sound in batch:
w = sound.waveform.astype(np.float32)
n_frames = max(1, len(w) // self.frame)
spectra = [np.abs(np.fft.rfft(w[i * self.frame:(i + 1) * self.frame] * self._window))
for i in range(n_frames)]
mean_spectrum = np.log1p(np.mean(spectra, axis=0))
vec = np.array([[float(b.mean()) for b in np.array_split(mean_spectrum, self.n_bands)]],
dtype=np.float32)
vec /= np.linalg.norm(vec) + 1e-9
out.append(types.SoundEmbedding(
embedding=vec,
timestamps=np.array([[0.0, sound.context.length / sound.context.sample_rate]], dtype=np.float32),
context=sound.context))
return out
@section(“2. The encoder contract: three methods, and the framework does the rest”)
def encoder_contract():
print(” MultiModalEncoder abstract methods a subclass must implement:”)
for name in sorted(encoder_lib.MultiModalEncoder.__abstractmethods__):
print(f” {name}”)
print(” final (framework-owned, do not override): setup(), encode()”)
t = np.arange(SR) / SR
fade = np.exp(-2.5 * t).astype(np.float32) # a decaying note, so the envelope is not flat
sound = types.Sound(waveform=(0.5 * fade * np.sin(2 * np.pi * 440 * t)).astype(np.float32),
context=types.SoundContextParams(id=”demo_000″, sample_rate=SR, length=SR))
for enc in (EnergyEnvelopeEncoder(), SpectralProfileEncoder()):
enc.setup()
emb = enc.encode([sound])[0]
stats = emb.encoding_stats # attached by encode(), not by our code
print(f”\n {type(enc).__name__:24s} -> {emb.embedding.shape} {emb.embedding.dtype}”
f” output_type={enc.output_type().__name__}”)
print(f” {”:24s} EncodingStats(input={stats.input_size_bytes:,} B, ”
f”embedding={stats.embedding_size_bytes} B, flops={stats.flops})”)
print(f” {”:24s} first 6 dims: {np.round(emb.embedding[0][:6], 3)}”)
print(“\n The envelope encoder sees the note decay; the spectral encoder sees one peak at 440 Hz.”)
try:
EnergyEnvelopeEncoder().encode([“not a Sound”])
except ValueError as e:
print(f”\n wrong input type is caught by _check_input_types: {e}”)
return “two encoders satisfying MultiModalEncoder”
encoder_contract()
We write two encoders by subclassing MultiModalEncoder, whose abstract methods are exactly three: _setup loads whatever the model needs, _check_input_types rejects anything that is not a Sound, and _encode turns a batch into SoundEmbedding objects. The framework owns setup and encode, and encode is what attaches EncodingStats to every result, so our code never fills that in by hand. EnergyEnvelopeEncoder averages energy in sixteen equal time slices and therefore describes only how loudness moves; SpectralProfileEncoder pools the mean log-magnitude spectrum into sixteen bands and therefore describes timbre. Both L2-normalise their output so a dot product is a cosine. Encoding one decaying note through each shows the difference immediately: the envelope encoder sees the decay, and the spectral encoder sees a single peak at 440 Hz.
N_PER_CLASS = 12
def synthesize(kind: str, index: int, take: int) -> types.Sound:
“””One second of audio. `take` 0 is the document, take 1 is a noisier recording of the SAME clip.
Two cues are deliberately separated: the spectrum says which class it is, and the amplitude
envelope – drawn per item, independent of class – says which item it is.
“””
item = np.random.default_rng(1000 + CLASSES.index(kind) * 100 + index)
control = 0.25 + 0.75 * item.random(8)
envelope = np.interp(np.linspace(0, 7, SR), np.arange(8), control).astype(np.float32)
t = np.arange(SR) / SR
if kind == “tone”:
w = np.sin(2 * np.pi * (380 + 80 * item.random()) * t)
elif kind == “chirp”:
f0, f1 = 200 + 50 * item.random(), 3200 + 400 * item.random()
w = np.sin(2 * np.pi * (f0 * t + 0.5 * (f1 – f0) * t ** 2))
else:
w = item.standard_normal(SR)
w /= np.sqrt(np.mean(w ** 2)) + 1e-9 # unit RMS: the envelope is the only loudness cue
take_rng = np.random.default_rng(50_000 + take * 10_000 + CLASSES.index(kind) * 100 + index)
w = (0.4 + 0.2 * take_rng.random()) * envelope * (w + 0.02 * take_rng.standard_normal(SR))
return types.Sound(waveform=w.astype(np.float32), context=types.SoundContextParams(
id=f”{kind}_{index:02d}” + (“” if take == 0 else “_take2″), sample_rate=SR,
length=SR, language=”en_us”, text=kind))
@section(“3. A synthetic corpus, encoded into MSEB embedding caches”)
def build_corpus():
corpus = [synthesize(k, i, 0) for k in CLASSES for i in range(N_PER_CLASS)]
queries = [synthesize(k, i, 1) for k in CLASSES for i in range(N_PER_CLASS)]
labels = {s.context.id: s.context.text for s in corpus + queries}
print(f” {len(corpus)} documents + {len(queries)} second takes of the same clips,”
f” {len(CLASSES)} classes, 1.0s each @ {SR} Hz”)
caches, query_caches = {}, {}
for enc in (EnergyEnvelopeEncoder(), SpectralProfileEncoder()):
enc.setup()
embeddings = enc.encode(corpus) # one batched call, like a real runner
caches[type(enc).__name__] = {e.context.id: e for e in embeddings}
query_caches[type(enc).__name__] = {e.context.id: e for e in enc.encode(queries)}
matrix = np.vstack([e.embedding for e in embeddings])
within, between = [], []
for i in range(len(corpus)):
for j in range(i + 1, len(corpus)):
sim = float(matrix[i] @ matrix[j])
(within if labels[corpus[i].context.id] == labels[corpus[j].context.id] else between).append(sim)
print(f” {type(enc).__name__:24s} cache of {len(embeddings)} embeddings, dim {matrix.shape[1]}”
f” mean cosine: same-class {np.mean(within):.3f} vs other-class {np.mean(between):.3f}”
f” (gap {np.mean(within) – np.mean(between):+.3f})”)
print(“\n Read that gap as a prediction: only the spectral encoder separates the classes at all.”)
print(” Steps 4-6 check whether the evaluators agree – and whether the gap is the whole story.”)
globals().update(CORPUS=corpus, QUERIES=queries, LABELS=labels, CACHES=caches, QCACHES=query_caches)
return f”{len(corpus)} documents + {len(queries)} queries encoded by 2 encoders”
build_corpus()
We synthesize a corpus in which two cues are deliberately separated. The spectrum says which class a clip belongs to, a tone, a chirp or noise, while the amplitude envelope is drawn per item and is independent of class, so it identifies which clip it is without saying anything about what it is. We normalize every waveform to unit RMS before applying the envelope, leaving the envelope as the only loudness cue. We render each of the thirty-six items twice, once as the document and once as a noisier second take of the same clip, and encode both sets with both encoders into MSEB embedding caches, the plain dictionaries from sound id to SoundEmbedding that every evaluator consumes. The mean same-class and other-class cosine similarities printed here read as a prediction about the next three steps: only the spectral encoder separates the classes at all.
“””Class embedding table (C, D): the mean unit vector of each class, as the evaluator’s `weights`.”””
rows = []
for name in CLASSES:
vecs = np.vstack([cache[i].embedding for i in cache if labels[i] == name])
mean = vecs.mean(axis=0)
rows.append(mean / (np.linalg.norm(mean) + 1e-9))
return np.vstack(rows).astype(np.float32)
@section(“4. ClassificationEvaluator: prototypes in, Score objects out”)
def classification():
table, example = {}, None
for name, cache in CACHES.items():
evaluator = classification_evaluator.ClassificationEvaluator(
class_labels=CLASSES,
weights=class_prototypes(cache, LABELS),
distance_fn=evaluator_lib.dot_product, # embeddings are L2-normalised -> cosine
top_k_value=2,
)
predictions = evaluator.compute_predictions(cache) # {id: per-class score vector}
references = [classification_evaluator.ClassificationReference(i, LABELS[i]) for i in cache]
table[name] = {s.metric: s.value for s in evaluator.compute_metrics(predictions, references)}
if name == “SpectralProfileEncoder”:
key = next(iter(predictions))
example = (key, np.round(list(predictions[key]), 3))
metric_names = list(next(iter(table.values())))[:6]
print(f” {‘encoder’:26s}” + “”.join(f”{m[:14]:>16s}” for m in metric_names))
for name, row in table.items():
print(f” {name:26s}” + “”.join(f”{row[m]:16.3f}” for m in metric_names))
print(f”\n compute_predictions returns one raw score per class, e.g. {example[0]!r} -> {example[1]}”)
print(f” ({CLASSES} – the argmax is the prediction, and top_k_value=2 also scores Top-2 Accuracy.)”)
print(” compute_metrics turns those into types.Score objects, which is what the leaderboard stores.”)
for name, row in table.items():
BENCH.setdefault(name, {})[“Accuracy”] = row[“Accuracy”]
winner = max(table, key=lambda k: table[k][“Accuracy”])
return “Accuracy: ” + “, “.join(f”{k} {v[‘Accuracy’]:.3f}” for k, v in table.items()) + f” (winner {winner})”
classification()
ClassificationEvaluator takes a table of class embeddings as its weights and a distance function, and we build the weights as class prototypes, the mean unit vector of each class. Its two methods separate cleanly: compute_predictions returns a raw score per class for every cached embedding, and compute_metrics turns those together with ClassificationReference labels into the list of Score objects that a leaderboard stores. Setting top_k_value to two adds Top-2 Accuracy alongside accuracy, balanced accuracy and the weighted precision, recall and F1. The spectral encoder classifies the corpus perfectly, and the envelope encoder lands well above chance but far below it, which is the ordering the cosine gap predicted.
def clustering():
evaluator = clustering_evaluator.ClusteringEvaluator()
examples = [clustering_evaluator.ClusteringExample(sound_id=i, label=LABELS[i])
for i in next(iter(CACHES.values()))]
print(f” {len(examples)} examples, KMeans with k = {len(CLASSES)} (inferred from the labels)”)
for name, cache in CACHES.items():
np.random.seed(0) # MiniBatchKMeans takes no random_state here:
scores = evaluator(cache, examples) # it falls back to NumPy’s global RNG, so pin that
# or an unstructured embedding space scores 0.01-0.08
# at random. The evaluator is callable.
BENCH.setdefault(name, {})[“VMeasure”] = scores[0].value
print(f” {name:26s} {scores[0].metric:12s} {scores[0].value:6.3f}”
f” [{scores[0].min}, {scores[0].max}] :: {scores[0].description}”)
print(“\n V-measure is the harmonic mean of homogeneity and completeness: 1.0 means the clusters”)
print(” recover the classes exactly, 0.0 means they carry no information about them. Note how much”)
print(” harsher it is on the envelope encoder than accuracy was – clustering gets no labels to lean on.”)
return “, “.join(f”{k} V={v[‘VMeasure’]:.3f}” for k, v in BENCH.items())
clustering()
ClusteringEvaluator asks the harder version of the same question, because it never sees a label at encode time: it runs KMeans over the cache. It scores the clusters against the labels with V-measure, the harmonic mean of homogeneity and completeness. The gap between the two encoders widens sharply here compared with classification, because a supervised prototype readout can exploit a faint cue that unsupervised clustering cannot find on its own. One practical detail is worth copying into any reproducible benchmark run: the evaluator constructs MiniBatchKMeans without a random_state, so it falls back to NumPy’s global generator, and without seeding that generator an unstructured embedding space scores anywhere between roughly 0.01 and 0.08 from run to run.
def retrieval():
print(” Task: each query is a NOISIER RECORDING OF ONE DOCUMENT, and exactly one document is correct.”)
print(” This is identity, not category – a different question from steps 4 and 5.\n”)
out = {}
for name, cache in CACHES.items():
doc_ids = list(cache)
docs = np.vstack([cache[i].embedding for i in doc_ids]).astype(np.float32)
queries = QCACHES[name]
searcher = retrieval_evaluator.BruteForceSearcher(candidates=docs, num_neighbors=10)
evaluator = retrieval_evaluator.RetrievalEvaluator(searcher=searcher, id_by_index_id=doc_ids, top_k=5)
predictions = evaluator.compute_predictions(queries)
references = [retrieval_evaluator.RetrievalReferenceId(
sound_id=q, reference_id=q.removesuffix(“_take2”)) for q in queries]
out[name] = {s.metric: s.value for s in evaluator.compute_metrics(predictions, references)}
q0 = next(iter(queries))
top = [item[“id”] for item in predictions[q0].items[:5]]
print(f” top-5 for query {q0!r} under {name}:”)
print(f” {top}”)
print(f” correct document at rank {top.index(q0.removesuffix(‘_take2’)) + 1}”
f” | neighbours of the same class: {sum(LABELS[i] == LABELS[q0] for i in top)}/5\n”)
metric_names = [“MRR”, “EM”, “RecallAt5”, “NDCG@10″]
print(f” {‘encoder’:26s}” + “”.join(f”{m:>14s}” for m in metric_names))
for name, row in out.items():
print(f” {name:26s}” + “”.join(f”{row[m]:14.3f}” for m in metric_names))
BENCH.setdefault(name, {})[“MRR”] = row[“MRR”]
print(“\n MRR is 1/rank of the correct document, EM is ‘it was rank 1’, RecallAt5 is ‘it was in the”)
print(” top 5’. NDCG@10 here is graded credit for the same single relevant document.”)
return “, “.join(f”{k} MRR={v[‘MRR’]:.3f}” for k, v in out.items())
retrieval()
RetrievalEvaluator answers a different question from the two before it, and we set the task up so that difference is visible. Each query is the noisier second take of exactly one document, so the target is identity rather than category. We index the document embeddings in a BruteForceSearcher, ask for predictions over the query cache, and pass one RetrievalReferenceId per query naming its single correct document. The evaluator returns MRR, exact match, recall at our top_k and NDCG at ten. The result inverts the previous two steps: the envelope encoder retrieves every clip at rank one, because the envelope is an item fingerprint. In contrast, the spectral encoder ranks slightly worse because clips of the same class look alike to it. The printed top-five lists make the mechanism plain, one neighbourhood class-random and the other class-pure.
def metric_layer():
truth = “the quick brown fox jumps over the lazy dog”
for hypothesis in [truth, “the quick brown fox jumped over a lazy dog”, “quick brown fox over lazy dog”]:
werrors, wtotal = metrics.compute_word_errors(truth, hypothesis)
cerrors, ctotal = metrics.compute_character_errors(truth, hypothesis)
print(f” WER {werrors / wtotal:5.3f} ({werrors}/{wtotal} words) ”
f”CER {cerrors / ctotal:5.3f} ({cerrors}/{ctotal} chars) {hypothesis!r}”)
print(“\n ranking metrics take (reference, ranked_ids):”)
ranked = [“doc_b”, “doc_a”, “doc_c”, “doc_d”]
for reference in [“doc_b”, “doc_a”, “doc_c”, “doc_z”]:
rank = ranked.index(reference) + 1 if reference in ranked else None
print(f” reference {reference!r:8s} rank {str(rank):4s}”
f” EM {metrics.compute_exact_match(reference, ranked):.1f}”
f” MRR {metrics.compute_reciprocal_rank(reference, ranked):.3f}”
f” nDCG@4 {metrics.compute_ndcg_at_k(reference, ranked, k=4):.3f}”)
print(” compute_ndcg_at_k assumes ONE relevant document and compares it by equality, so pass a”)
print(” string, not a list – a list reference silently scores 0.0 while MRR still looks fine.”)
print(“\n embedding-space distances used by the reconstruction and stability tasks:”)
a = np.random.default_rng(1).standard_normal((8, 4)).astype(np.float32)
for label, b in [(“identical”, a), (“noisy”, a + 0.1 * np.random.default_rng(2).standard_normal(a.shape))]:
lp = metrics.compute_lp_norm(a, b, p=2)
dtw = metrics.compute_dynamic_time_warping_distance(a, b)
print(f” {label:10s} L2 {json.dumps({k: round(float(v), 3) for k, v in lp.items()})}”
f” DTW {json.dumps({k: round(float(v), 3) for k, v in dtw.items()})}”)
return “WER/CER, EM/MRR/nDCG, Lp and DTW distances”
metric_layer()
We call the metric functions directly, without an evaluator around them, because they are the layer the task families share. compute_word_errors and compute_character_errors take two strings and return errors and totals separately, so the caller decides how to aggregate a corpus. The ranking metrics take a reference and a ranked list of identifiers, and comparing exact match, reciprocal rank and nDCG over the same ranking shows what each one pays for position. One sharp edge is worth naming: compute_ndcg_at_k assumes a single relevant document and compares it by equality, so passing a list of relevant ids silently scores zero. In contrast, MRR, which does accept a list, still looks correct. We close with compute_lp_norm and compute_dynamic_time_warping_distance, the embedding-space distances behind the reconstruction and stability tasks.
def segmentation():
evaluator = segmentation_evaluator.SegmentationEvaluator(tau=0.05)
print(” Here a ‘segment’ carries a TERM, not a vector: SoundEmbedding.embedding holds N strings”)
print(” and timestamps holds their N [start, end] spans. tau=0.05 -> a boundary may be 50 ms out.\n”)
TERMS = [(“weather”, 0.00, 0.30), (“in”, 0.30, 0.65), (“boston”, 0.65, 1.00)]
truth = [segmentation_evaluator.Segment(embedding=term, start_time=s, end_time=e, confidence=1.0)
for term, s, e in TERMS]
references = [segmentation_evaluator.SegmentationReference(example_id=”utt_0″, segments=truth)]
def prediction(spans):
return {“utt_0″: types.SoundEmbedding(
embedding=np.array([term for term, _, _ in spans]), # N strings
timestamps=np.array([[s, e] for _, s, e in spans], dtype=np.float32), # N [start, end]
context=types.SoundContextParams(id=”utt_0”, sample_rate=SR, length=SR),
scores=np.ones(len(spans), dtype=np.float32))} # confidences
candidates = {
“exact”: TERMS,
“50 ms out”: [(“weather”, 0.00, 0.28), (“in”, 0.28, 0.67), (“boston”, 0.67, 1.00)],
“right words, wrong places”: [(“weather”, 0.00, 0.45), (“in”, 0.45, 0.80), (“boston”, 0.80, 1.00)],
“right places, wrong words”: [(“weather”, 0.00, 0.30), (“on”, 0.30, 0.65), (“austin”, 0.65, 1.00)],
}
shown = [“TimestampsAccuracy”, “EmbeddingsAccuracy”, “TimestampsAndEmbeddingsAccuracy”, “WordErrorRate”, “mAP”]
print(f” {‘prediction’:28s}” + “”.join(f”{m[:13]:>15s}” for m in shown))
for label, spans in candidates.items():
result = evaluator.compute_scores(prediction(spans), references) # per-example scores
scores = {s.metric: s.value for s in evaluator.compute_metrics(result)} # aggregated Scores
print(f” {label:28s}” + “”.join(f”{scores[m]:15.3f}” for m in shown))
print(“\n The last two rows are the point: one metric cannot tell ‘knew the words, missed the timing'”)
print(” from ‘nailed the timing, heard the wrong words’. Timestamps and embeddings are scored apart,”)
print(” and only TimestampsAndEmbeddings credits getting both right at once.”)
return “boundary + term scoring at tau=50 ms”
segmentation()
SegmentationEvaluator scores what was said and where it was said as separate quantities, and it uses the string form of SoundEmbedding that step 1 mentioned: the embedding array holds one term per segment and the timestamps array holds their spans. Its flow is two-stage, compute_scores over predictions and references first, then compute_metrics over that result. We score four candidate segmentations of the same phrase against one ground truth with a tolerance of fifty milliseconds. Exact and fifty-milliseconds-out both score perfectly, which is what the tolerance is for. The last two rows carry the lesson: right words in the wrong places scores one on embeddings and zero on timestamps, right places with the wrong words does the reverse, and only the combined metric credits getting both right at once.
def task_metadata():
cache = CACHES[“SpectralProfileEncoder”]
evaluator = classification_evaluator.ClassificationEvaluator(
class_labels=CLASSES, weights=class_prototypes(cache, LABELS), top_k_value=2)
references = [classification_evaluator.ClassificationReference(i, LABELS[i]) for i in cache]
scores = [s for s in evaluator.compute_metrics(evaluator.compute_predictions(cache), references)
if s.metric in (“Accuracy”, “Weighted F1-Score”)]
metadata = types.TaskMetadata(
name=”SyntheticToneClassification”,
description=”Three-way classification of synthetic tones, chirps and noise”,
reference=”https://github.com/google-research/mseb”,
type=”Classification”,
category=”sound”,
main_score=”Accuracy”,
revision=”1″,
dataset=types.Dataset(path=”synthetic/in-notebook”, revision=”1″),
scores=scores,
eval_splits=[“test”],
eval_langs=[“en_us”],
)
print(f” TaskMetadata: {metadata.name} type={metadata.type} main_score={metadata.main_score!r}”)
print(f” dataset={metadata.dataset.path!r} rev {metadata.dataset.revision}”
f” splits={metadata.eval_splits} langs={metadata.eval_langs}”)
print(f” scores={[f'{s.metric}={s.value:.3f}’ for s in metadata.scores]}”)
try:
types.TaskMetadata(**{**{f.name: getattr(metadata, f.name) for f in metadata.__dataclass_fields__.values()},
“scores”: []})
except Exception as e:
print(f” validated at construction: {type(e).__name__}: {e}”)
columns = [“Accuracy”, “VMeasure”, “MRR”]
print(f”\n One row per encoder, one column per task family:”)
print(f” {‘encoder’:26s}” + “”.join(f”{c:>12s}” for c in columns) + ” what it measures”)
for name, row in BENCH.items():
print(f” {name:26s}” + “”.join(f”{row[c]:12.3f}” for c in columns)
+ (” timbre -> class” if “Spectral” in name else ” loudness over time -> identity”))
flips = [c for c in columns
if (max(BENCH, key=lambda n: BENCH[n][c]) != max(BENCH, key=lambda n: BENCH[n][“Accuracy”]))]
print(f”\n The winner changes column to column ({‘, ‘.join(flips)} goes the other way). That is the whole”)
print(” argument for a MASSIVE benchmark: a single headline number would have hidden it. An encoder”)
print(” that cannot name a sound can still recognise it, and vice versa.”)
print(“\n A real submission runs mseb.runner over an mseb.task against a published dataset and writes”)
print(” these same Score objects to JSON; the layers above are exactly what it exercises.”)
return f”TaskMetadata + {len(BENCH)} encoders x {len(columns)} task families”
task_metadata()
We assemble the TaskMetadata that a real submission carries, the name, type, category, main score, dataset path and revision, evaluation splits and languages, together with the Score objects themselves, and it validates at construction in the same way a Score does, rejecting an empty score list. Then we put all results so far into one table: one row per encoder and one column per task family. The winner changes from column to column: the encoder that cannot name a sound still recognises it, and the encoder that names every sound correctly confuses clips that belong together. A single headline number would have hidden that completely, which is the argument for a benchmark that is massive in tasks rather than only in data.
for name, res in RESULTS.items():
print(f” {name:<74s} {res}”)
print(“””
Where to go next
– Swap in a real encoder: mseb/encoders/ ships wav2vec, Whisper, CLAP, EnCodec and SoundStream
wrappers, plus CascadeEncoder for speech-to-text-to-embedding chains. Only the three methods
from step 2 change; every evaluator above keeps working.
– Run a published task: mseb.runner drives mseb.task over a real dataset with apache-beam; the
task families live in mseb/tasks/ (classification, retrieval, reranking, transcription,
segmentation, clustering, reasoning, brain_encoding, stability).
– Compare against the leaderboard: https://huggingface.co/spaces/google/mseb-leaderboard
– Read the contract you implemented: mseb/encoder.py and mseb/evaluator.py are ~500 lines total.
“””)
The summary prints the one-line result each section returned, then points at the three directions this notebook opens: swapping in one of the real encoders shipped in the package, wav2vec, Whisper, CLAP, EnCodec, SoundStream or the cascade wrapper, which changes only the three methods from step 2 and leaves every evaluator working; running a published task through mseb.runner against a real dataset; and comparing the result with the public leaderboard.
In conclusion, we treated MSEB as what it is, a contract plus a set of evaluators, and drove it end to end without downloading a dataset or touching an accelerator. Implementing three methods was enough to make our own code a first-class citizen of the benchmark, and the framework handled batching, statistics, and validation from there. The evaluators asked genuinely different questions of the same embeddings: classification and clustering ask what a sound is, retrieval asks which sound it is, and segmentation asks what was said and where, scored apart so a timing failure and a recognition failure never hide inside one average. Our two encoders traded places depending on the question asked, and we carry that result forward, because a single number cannot rank a sound embedding. The next step is to substitute a real encoder for our toy ones and re-run the same evaluators, since none of the scoring code above changes when the embeddings improve.
Check out the GitHub Repo with Full Codes. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.