
Sarvam Launches Sarvam Token Factory: Bringing India-Hosted Inference to 8 Open Models
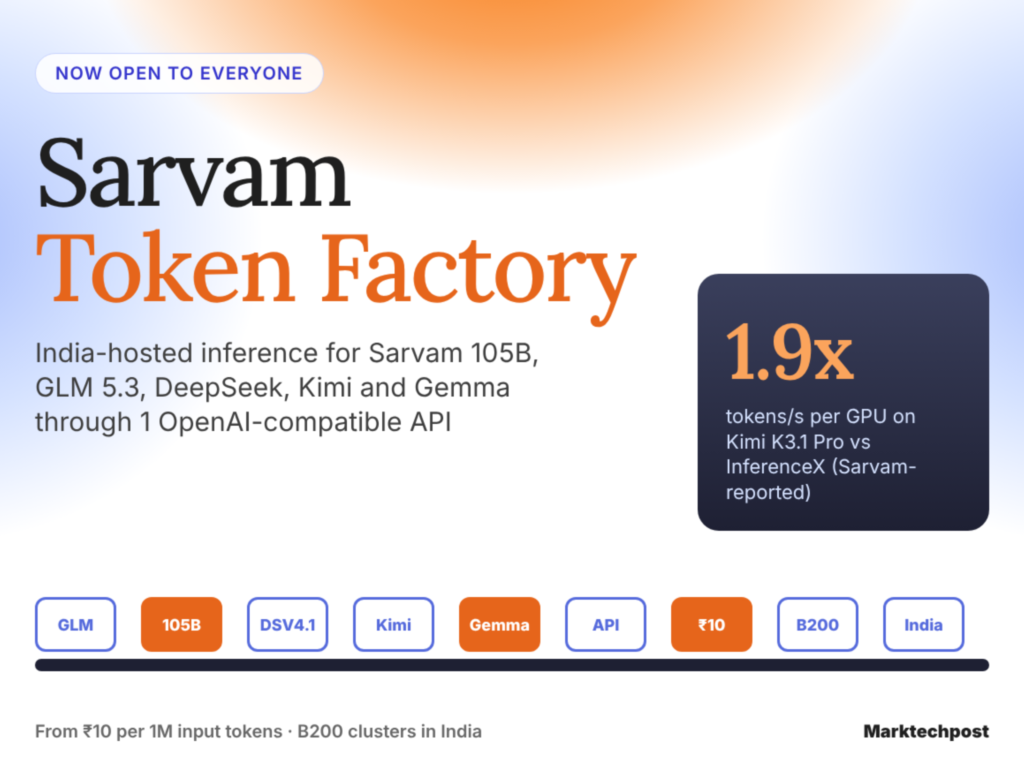
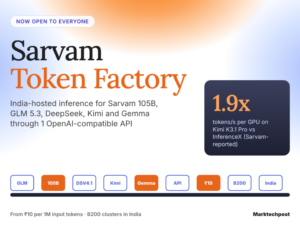
Sarvam has opened Sarvam Token Factory to everyone. Sarvam Token Factory is an inference platform from Sarvam that serves its own models and open-weight models from GPU clusters in India. Developers reach every model through one OpenAI-compatible API. For India-based teams, this means low-latency tokens without sending traffic to overseas clouds. You can check the deployment options and specs here through our GPULeaderboard.com chrome extension.
TL;DR
Size: 8 models listed at launch, including Sarvam 105B (105B total, 9B active, 128K context), GLM 5.3, DeepSeek V4.1 Flash 1017, Kimi K3.1 Pro and Gemma 4 31B.
Runs on: NVIDIA B200 clusters in India. Sarvam 105B now fits on 1 B200 per replica. On-premise deployment is offered to enterprises.
Performance: Fastest first token from Mumbai on most tested cases, per Sarvam’s own measurements.
Best: Kimi K3.1 Pro at 6,177 tokens/s per GPU vs 3,213 for InferenceX, at 70 tokens/s per user (1.9x).
What is Sarvam Token Factory?
It is a managed inference stack, not a single model. Sarvam first previewed it as Sarvam Inference at its Epoch event. The launch post lists 8 models: Sarvam 105B, GLM 5.3, GLM 5.3 Flash, DeepSeek V4.1 Flash 1017, DeepSeek V4 Pro, Kimi K3, Kimi K3.1 Pro and Gemma 4 31B.
The docs split them into 2 groups. Pay-as-you-go models run on shared endpoints. DeepSeek V4 Pro, Kimi K3.1 Pro, Qwen 3.8 27B, Clef and EmbeddingGemma 2 need Provisioned Throughput, enabled per organisation.
How does it work?
The stack has 3 layers around a shared cache:
Control plane: a cache-aware router, admission control and a planner.
Inference engine: separate GPU pools for prefill and decode.
Cache: GPU memory plus a shared G3 store built on Mooncake.
It builds on vLLM, SGLang, Dynamo, Mooncake, NIXL, DeepEP, DeepGEMM and FlashInfer. An orchestrator agent proposes experiments, and an engineer approves each deployment.
Caching drives most of the gains. DeepSeek V4.1 Flash serves 450B+ tokens per day, with 95.7% of prompt tokens served from cache. On GLM 5.3, the planner cut prefill GPU-hours from 32.3 to 17.1 under the same replayed load.
For Sarvam 105B, MXFP8 weights plus speculative decoding raised output throughput about 2.2x. That cut each replica from 2 B200s to 1. Sarvam says none of these changes reduced accuracy.
How fast is it? Benchmarks
All numbers below come from Sarvam’s launch post. They are self-reported.
Sarvam 105B: 0.2 s first token and 330 tokens/s for a single user.
Gemma 4 31B (10K prompt, Mumbai): 0.40 s first token and 308 tokens/s, vs 2.00 s and 193 tokens/s at the only other provider.
Kimi K3.1 Pro (16 B200s): 6,177 vs 3,213 tokens/s per GPU against InferenceX at 70 tokens/s per user.
Heavy agent load (72 sessions): median first token 0.8 s vs 11.6 s for InferenceX.
GLM 5.3 Flash (64 sessions): p99 first token 3.2 s vs 14.1 s for stock vLLM and Dynamo.
The results are not a clean sweep. On DeepSeek V4.1 Flash with a 10K prompt, Together posts 0.71 s first token vs Sarvam’s 0.90 s. Together also streams faster, at 278 tokens/s vs 130 on Sarvam Standard.
How much does it cost?
Prices are in Indian rupees per 1M tokens, per the docs:
Introductory pricing runs through the end of 2026. A faster DeepSeek Interactive endpoint costs ₹25 input and ₹105 output. Provisioned model rates are not published on the docs page.
How does it compare with other inference providers?
Key Takeaways
Sarvam Token Factory serves Sarvam and open-weight models from India via one OpenAI-compatible API.
Sarvam 105B starts at ₹10 input and ₹25 output per 1M tokens.
Sarvam reports 1.9x per-GPU throughput over InferenceX on Kimi K3.1 Pro.
Together still beats it on DeepSeek V4.1 Flash streaming speed.
All benchmark numbers are self-reported.
Check out the technical blog, the API docs and the launch post on X. You can check the deployment options and specs here through our GPULeaderboard.com chrome extension.
Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.